



Applied AI Researcher @ Translated · PhD Student @ Sapienza University of Rome
Large-scale generative models · Representation learning · Audio & music ML


I train large generative models, at work and in my research.
At Translated, in the Foundation Models team, I work on pre-training, continued pre-training and distillation of large-scale multilingual language models. At Sapienza, as a PhD student, I study generative models for audio and how to give their latent spaces semantic structure. Before Translated, I worked on production LLM systems, including a RAG assistant deployed for the Italian Ministry of Education.
I like owning the whole stack: data curation, model design, custom CUDA kernels, distributed training on HPC and careful evaluation. I'm also a musician, which is where the audio obsession comes from.
Paper · Project page · Weights
|
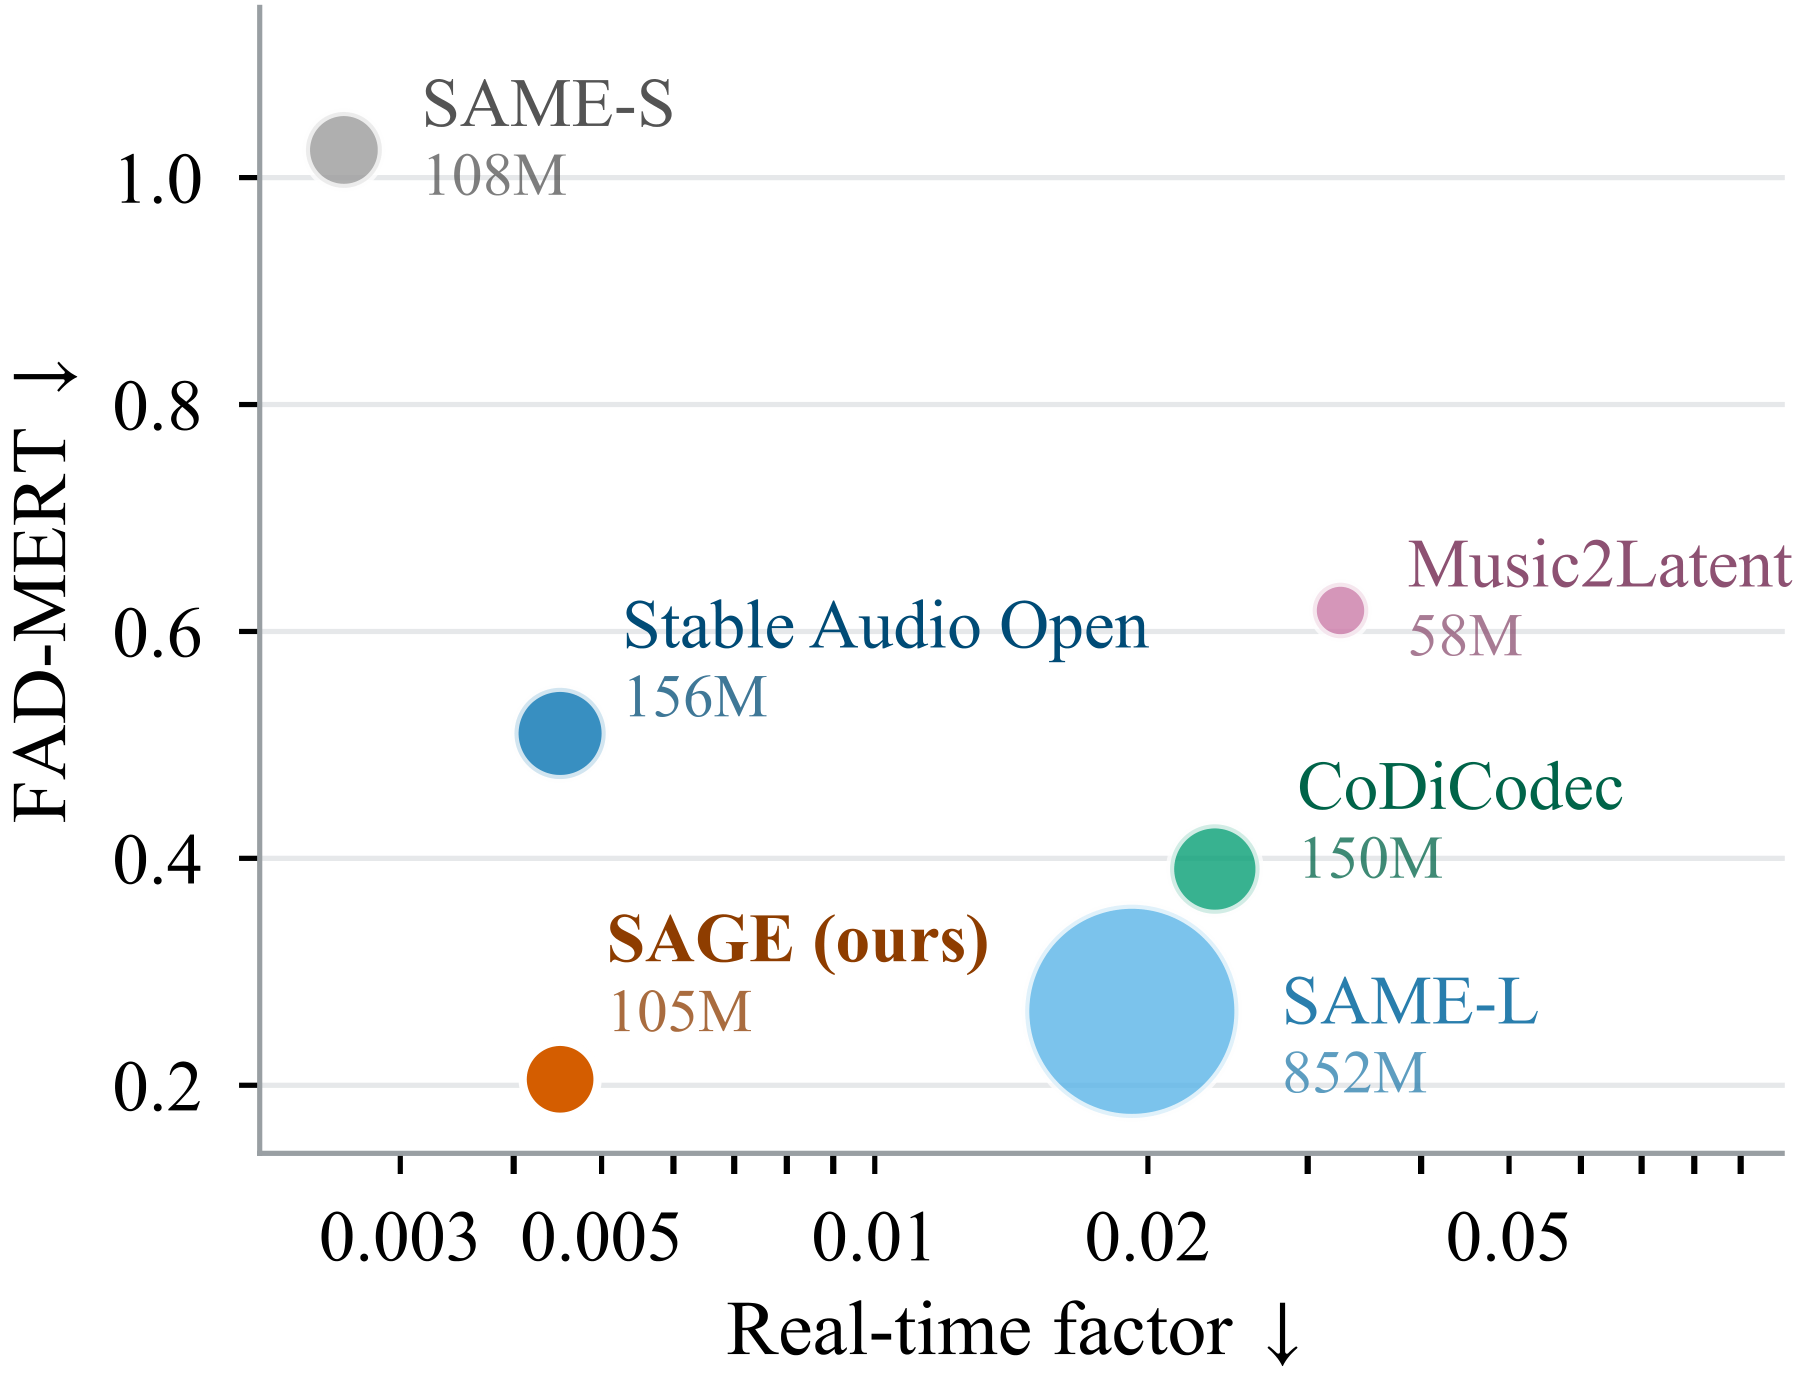
A compact 105M-parameter VAE for 44.1 kHz stereo music. A Swin Transformer V2 encoder and decoder work on the STFT, and LAION-CLAP semantic distillation shapes the latent space.
Supported by an ISCRA allocation on Leonardo and a €5,000 Google Cloud Research Credits award. |
| Project | What it is | Highlight |
|---|---|---|
| Audio2PianoRoll | Automatic music transcription with CQT and a custom U-Net | 83% F1 on GuitarSet |
| MusicBuddy | Real-time AI accompanist: an LSTM and a music-theory "Ear" follow your MIDI playing and answer with chords | ~3 ms per chord decision · demo |
| Audio Style Transfer | Piano ↔ violin transfer through latent disentanglement | Complex-valued representations |
| VectorRAG vs GraphRAG | Benchmark of vector, graph and hybrid RAG for enterprise retrieval | 10× fewer tokens at 0.84 faithfulness |
microsoft/Swin-Transformer #389
Fused window CUDA kernels: fixed an out-of-bounds read that silently corrupts outputs on any non-square input, generalised the kernels to non-square windows, per-axis shifts and bfloat16, and ported them to ROCm, where they had never compiled. Bit-exact against eager on NVIDIA RTX 3080 and AMD MI300X, with a GPU-free test suite running in CI.

Large-scale training: PyTorch (DDP) · Megatron Bridge · Lightning · Hydra · SLURM / HPC · Weights & Biases
Kernels & systems: CUDA · ROCm · C++ · Python
LLMs: Hugging Face Transformers · PEFT / QLoRA · distillation · LLM evaluation · RAG
Audio: torchaudio · librosa · neural audio codecs · MIDI
Happy to talk about audio generative models, large-scale training or music. The best way to reach me is email.