
Narrated presentations, cut to the word.
DeckTalk makes a narrated video from a markdown script and HTML slides.
Each reveal starts on the word that introduces it.
If you change a sentence, DeckTalk voices only that section again.
DeckTalk is for lecturers, course authors, developer advocates, and the agents that help them.


Quickstart ·
Docs ·
Requirements and costs ·
Reference card for agents ·
Changelog
Agents can read llms.txt.
You need Python 3.12 or later. These steps use uv, a Python package manager. If you use pipx, run pipx install decktalk in step 1 instead.
-
Install DeckTalk.
uv tool install decktalkuv ends with
Installed 1 executable: decktalk. -
Download Chromium, ffmpeg, and KaTeX. You do this one time per machine.
decktalk setupOn Linux, this step asks for sudo. The last line is
setup complete. -
Create the scaffold, a complete example project.
decktalk init my-lesson -
Go into the project.
cd my-lesson -
Build the video without an account.
decktalk build --silentThe build ends with
builtand the path ofbuild/out/my-lesson.mp4. The build took 224.4 seconds on a MacBook Pro with Apple M5 Pro and 64 GB memory, because recording runs in real time. -
Copy the example settings file.
cp .env.example .env -
In
.env, set your ElevenLabs API key and voice id. DeckTalk never prints the key. -
Build the video with your voice.
decktalk buildThis build spends ElevenLabs credits for every section. It writes the video, SRT and VTT captions, and one chapter per section. What spends credits lists the cost.
The scaffold is a lesson in nine sections, two of them optional clips. The quickstart shows the output of each step and what the example video shows.
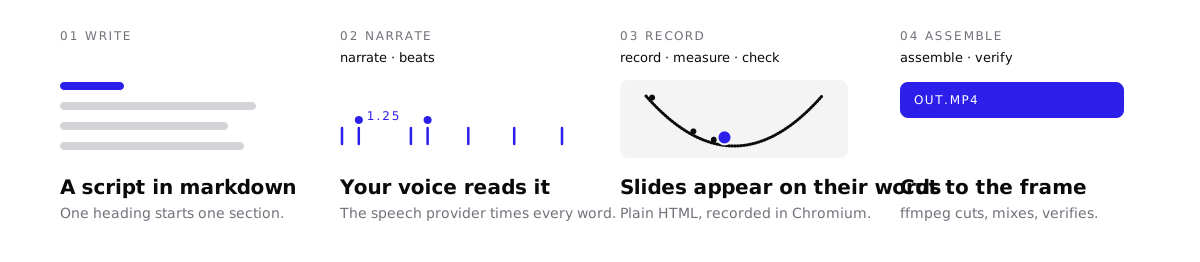
You write four files. One cue id per reveal, such as 1.1bowl, ties the script, the cues, and the page together.
| File | What it holds |
|---|---|
script.md |
What the voice says, under one ## N. Title heading per section. |
decktalk.toml |
The project file. It ties each section to a page or to a clip of your own. |
cues.json |
The phrase that each reveal starts on. |
A page in deck/ |
The slides, as plain HTML. |
The narrate stage writes a words file with the start and end of every spoken word. If a cue phrase is not in the spoken words, the build stops and names the cue. Your first deck writes one section in all four files.

A browser does not start recording at a known time, so DeckTalk does not use a timer. The recorder covers the page in magenta until the narration starts. The first frame without magenta is narration t=0, on Linux, macOS, and Windows.
decktalk verify then measures every reveal in the finished video. This sample comes from a silent build of the scaffold.
check                 cue       at   chg %   ctl %   offset     a/v  result
1:1.1bowl            1.25     1.25    0.93    0.00    +30ms   +31ms  changed
3:3.4name           84.72   123.32    2.76    0.00     +0ms    -4ms  changed
8:7.1checked        10.03   238.31    0.83    0.00    +10ms    +3ms  changed
The offset column is the time from the cue time to the onset of the reveal, in milliseconds. Verify defines every column and limit.
- Software. DeckTalk needs Python 3.12 or later, on Linux, macOS, or Windows.
decktalk setupdownloads the rest. - Accounts. A silent build needs no account. A voiced build needs an ElevenLabs API key and a voice id.
- Cost. Every ElevenLabs plan can call the API. The free plan has limits for a video you publish.
Requirements and costs lists every download and every command that spends credits.
| Tool | Timing comes from | Slides are | After you edit one sentence |
|---|---|---|---|
| DeckTalk | the spoken words, one time per word | your HTML | DeckTalk voices one section again. build --only N records only that section. |
| Remotion, Motion Canvas | frame numbers or seconds in code, by default | code | You time the change again by hand and render again. |
| Manim | seconds in code, or bookmarks in the narration with manim-voiceover | code | With manim-voiceover, bookmarks follow the new text. You still render the scene again in Python. |
| Descript | a recording you made | your screen | Overdub voices the new words. The screen recording does not move with them. |
| Synthesia, HeyGen | the avatar's speech | their avatar and scenes | You generate the video again. |
The FAQ has the full comparison. Every build also gives you these parts:
- A free silent build. Every stage runs with no key, and a click marks each word.
- Cached narration. DeckTalk voices a section again only when it changes.
- Captions and chapters. Every build writes SRT, VTT, and chapters.
- A soundscape. Add an underscore, an ambience bed, and sound effects.
- Loudness. DeckTalk normalizes the mix to -16 LUFS.
- Checked output.
checkandverifycatch bad recordings and late reveals.
DeckTalk is alpha, and a minor release can still break things. One person maintains it.
CI runs the unit tests and a full offline build on Linux for every push to main and every pull request. CONTRIBUTING lists the macOS and Windows runs.
- Report bugs and ask questions in Issues.
- Report a vulnerability privately. SECURITY.md explains how.
- The changelog lists every release.
The docs are at docs.decktalk.app.
- Install and build a first video: Quickstart
- Write your own section: Your first deck
- Give an agent the whole contract: Reference card for agents
To work on DeckTalk itself, start with CONTRIBUTING.md.
Apache-2.0. Made by Jacob Beaudin.