




V-BAR (Verified Benchmark for Autonomous Rendezvous) tests the software that steers one spacecraft up to another, and grades each flight on whether it arrived, whether it kept a safe distance, and how much fuel it used against the least possible. It has no AI of its own: you bring the controller, whether hand-written code, a trained neural network or an AI model reached with your own API key, and V-BAR flies it on simulated missions from the same starting points as every other controller, so results can be compared.
V-BAR is a headless Python benchmark for spacecraft rendezvous and proximity-operations controllers. Classical guidance laws, reinforcement learning agents and LLM agents fly the same scenarios and are scored with the same metrics.
pip install vbarfrom vbar import ApproachConfig, ApproachEnv, run_episode
from vbar.agents import PDAgent
env = ApproachEnv(ApproachConfig(start_state=(0, -400, 0, 0, 0, 0)))
result = run_episode(env, PDAgent())
print(result["captured"], result["keep_out_violated"], result["dv_used_mps"])This flies the PD baseline from 400 m behind the target to the hold point 100 m behind it, about
620 s of simulated flight, and prints True False 2.41...: it arrived, it never entered the
keep-out zone, and it used 2.4 m/s of delta-v.
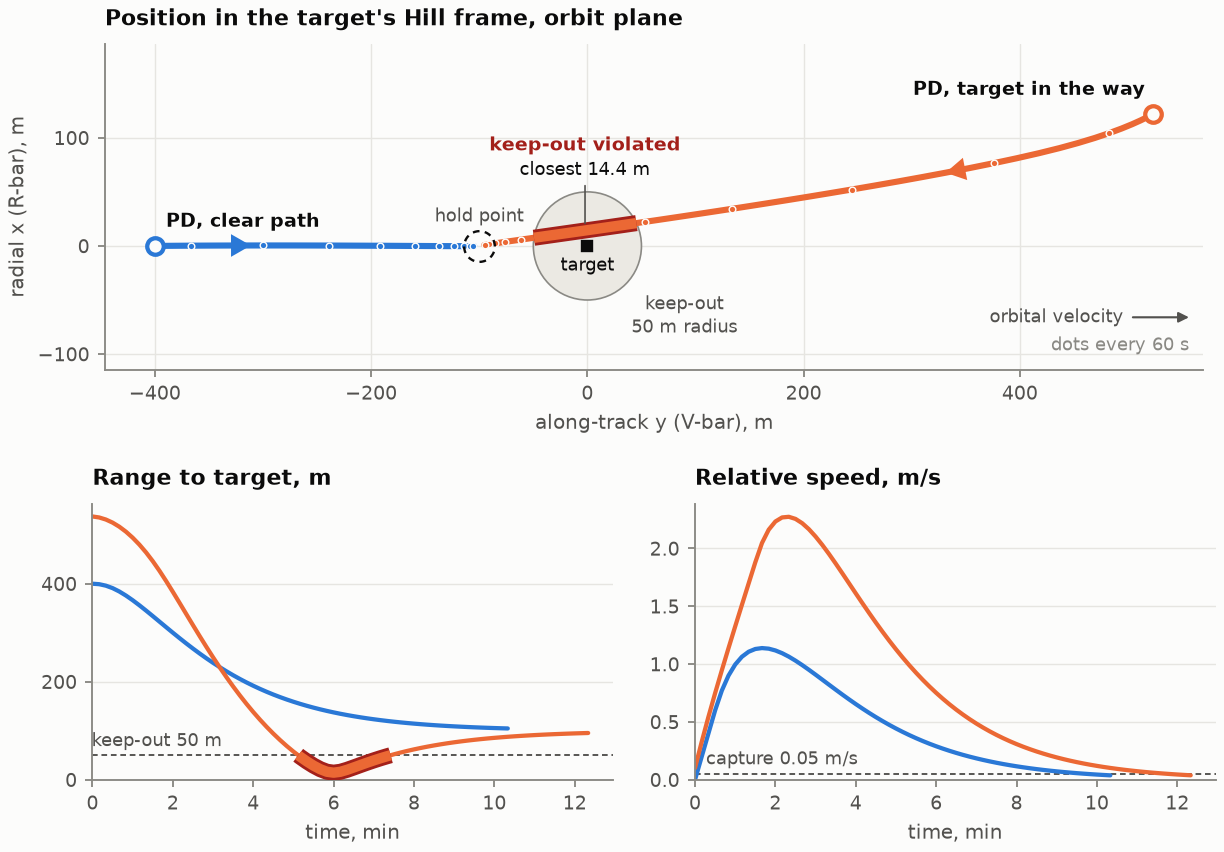
The PD baseline reaches the hold point from behind the target (blue) but flies through the keep-out zone from ahead of it (orange), closing to 14.4 m.
The quick start notebook runs without a local install. It installs the package from PyPI, flies this baseline, prints its metrics and rebuilds a two-episode results table with the evaluation harness (docs/evaluation.md).

pip install vbar installs the core package, which needs Python 3.12 or later and depends on
numpy, scipy and gymnasium. Each optional feature has an extra:
| Extra | Install | Adds |
|---|---|---|
plot |
pip install "vbar[plot]" |
plots and animations |
onnx |
pip install "vbar[onnx]" |
ONNX policy export and inference |
replay |
pip install "vbar[replay]" |
replays for the Rerun viewer |
llm |
pip install "vbar[llm]" |
python-dotenv, which reads model settings from a .env file (LLM controllers); not in the 0.7.0 release, where pip install python-dotenv does the same |
basilisk |
pip install "vbar[basilisk]" |
agreement checks against Basilisk |
orekit |
pip install "vbar[orekit]" |
agreement checks against Orekit; needs a Java runtime (11 or later) on JAVA_HOME |
To work on V-BAR itself, see CONTRIBUTING.md.
The vbar command comes in the next release; it is not in the 0.7.0 release on PyPI, so
pip install vbar does not give it. To try it now, install the development version from this
repository (this needs git):
pip install git+https://github.com/jamilhammoudeh/vbar
vbar setup
vbar run
vbar setup lists the providers it can connect to (vbar setup --list), asks you to pick one and
paste your API key, and checks that it works. A built-in controller needs no key, so you can skip
this step to try V-BAR first. vbar run asks which mission to fly and which controller flies it,
then prints a scorecard. For example, vbar run --scenario approach-vbar --controller pd --seeds 3 --no-save flies the built-in PD controller and prints, among other lines:
Did not pass
It reached the hold point and held it, but flew through the keep-out
zone on the way.

Arrival: met
  Held the hold point for 10 min 3 s and ended 3 cm from it. Goal met 20
  min 57 s after the start.
  Needed: within 5 m and slower than 0.05 m/s, for 10 min.
Keep-out zone: not met
  Inside the 50 m zone for 1 min 43 s, 36.6 m from the target at the
  closest.
  Needed: never inside.
Cost: free
  Built-in controller, no calls to any AI model.
A run with an AI model stops when it reaches a dollar cap ($1.00 by default; --max-usd changes
it). If the vbar command is not on your PATH, python -m vbar does the same. The commands are
described in
docs/command-line.md;
where the key is kept is in
docs/setup.md.
Early development (0.7). The dynamics, spacecraft, sensor and constraint layers are validated (see Tests). Interfaces may change before 1.0; what each release added, changed and fixed is in CHANGELOG.md.
KSPDG, the main existing environment for this kind of work, runs on Kerbal Space Program in real time and needs a copy of the game. V-BAR is a plain Python package that runs much faster than real time on Linux, macOS and Windows, so experiments with hundreds of seeds and many controllers are practical. Its physics is checked against closed-form solutions and published textbook examples, so a result reflects the controller and not a simulator error.
Everything is in the target's Hill frame (also called RIC, RSW or RTN), centred on the target and rotating with its orbit:
- x: radial, pointing away from Earth (the R-bar)
- y: along-track, the direction the target is moving (the V-bar); "behind the target" is -y
- z: orbit normal, completing a right-handed frame
States are [x, y, z, vx, vy, vz] in metres and metres per second, with velocities measured in
the rotating frame. All units are SI and angles are in radians. The ISS-style LVLH frame used in
much of the operations literature orders and signs the axes differently;
vbar.conventions.hill_to_iss and iss_to_hill convert between the two.
The chaser must reach a hold point 100 m behind the target and stop there without entering a 50 m
keep-out sphere around the target. The target is on a circular 500 km orbit. Defaults, all set in
ApproachConfig:
| Item | Default |
|---|---|
| Start | position uniform in x in [-200, 200] m, y in [200, 600] m, z in [-50, 50] m; each velocity component in [-0.1, 0.1] m/s; or a fixed start_state |
| Action | 3 numbers in [-1, 1], scaled by max_accel = 0.02 m/s^2 per axis, held for one step; action_mode="accel" or "thrust" takes m/s^2 or newtons instead |
| Observation | the chaser's relative state [x, y, z, vx, vy, vz] from the navigation sensor, exact by default (PerfectNav); GaussianNav, RangeScaledNav and GaussMarkovNav add errors, and observation_channels appends time left, propellant left and pending commands |
| Spacecraft | 500 kg, Isp 220 s, propellant following the rocket equation; per-axis ("box") or total ("ball") thrust limit, minimum impulse bit, actuation delay, constant-acceleration or constant-thrust drive and thrust execution error are options |
| Step and length | dt = 10 s, at most 360 steps (one hour) |
| Success | within 5 m of the hold point and slower than 0.05 m/s; the episode ends on success |
| Keep-out | checked in continuous time: 20 samples per step, refined between them, with a certified lower bound; entering it does not end the episode unless terminate_on_violation is set |
Each run reports whether it captured, whether and in how many steps it entered the keep-out zone,
the minimum range to the target, the final distance to the hold point, delta-v used (each step's
delta-v summed, the usual proxy for propellant), flight time and wall-clock time, plus the
intervention count when a safety filter wraps the agent. run_episode also returns the full true
state and action history and the seed of the agent's random stream. Propellant used, mass and the
certified bound on the keep-out margin are in info.
The environment propagates with Clohessy-Wiltshire dynamics by default;
ApproachConfig(dynamics="twobody") or "twobody_j2" selects one of the nonlinear models below.
Benchmarks need many runs, not one. With the default random starts, which put the chaser 200 to 600 m ahead of the target so the target sits between it and the hold point:
import numpy as np
from vbar import ApproachEnv, run_many
from vbar.agents import PDAgent

results = run_many(ApproachEnv(), PDAgent(), seeds=range(100))
print(np.mean([r["captured"] for r in results]), np.mean([r["keep_out_violated"] for r in results]))
On every default seed the PD baseline reaches the hold point and flies through the keep-out zone,
because it ignores the target. That gap is what safety filters and better controllers are measured
against. In a clone of the repository, python examples/v0_demo.py shows both cases and saves a
plot to outputs/ (needs the plot extra).
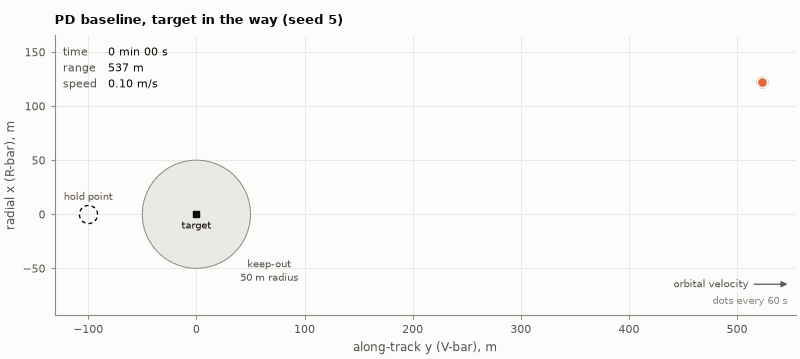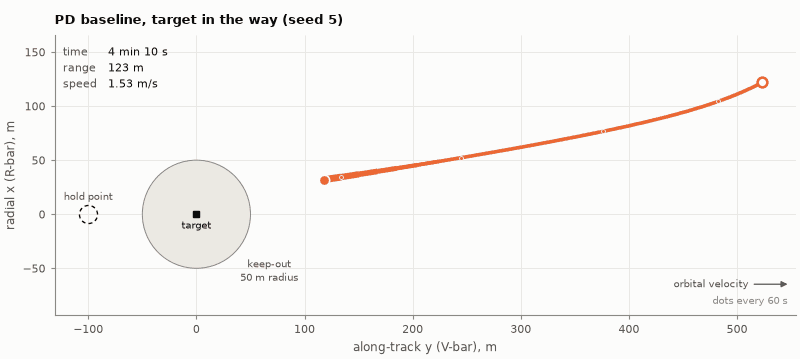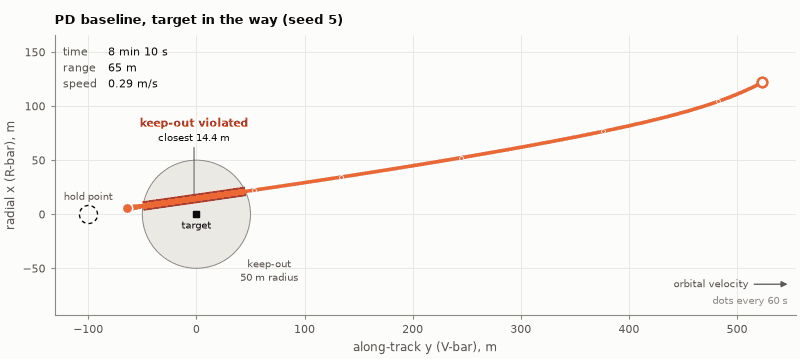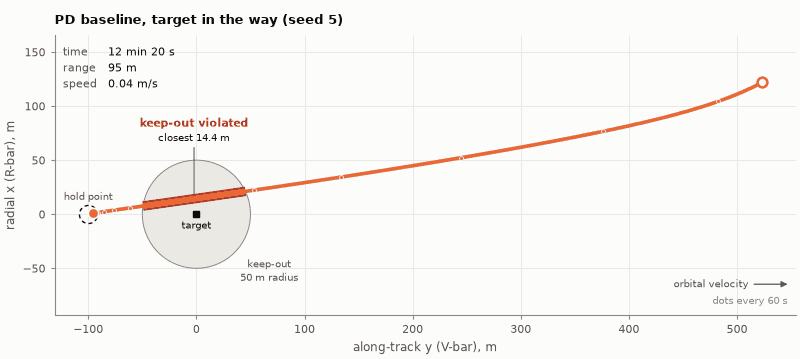
The orange run animated: it spends about 2.3 minutes inside the keep-out zone.
python examples/readme_figures.py regenerates this animation and the figure in the quick start
(docs/viz.md).
vbar.metrics.record_episode(env, agent, seed) records a run and vbar.metrics.evaluate(episode)
scores it from the true trajectory in continuous time: mission (success, terminal errors, time,
progress, docking contact, hold dwell), efficiency (delta-v in both norms, propellant, burns, duty
cycle, chatter, the optimality gap against oracle bounds), constraint margins with violation depth
and duration, passive safety and collision-avoidance availability, thruster plume, safety-filter
and agent metrics, a composite score with its breakdown, and a failure label for failed runs.
These are the benchmark's scores; the keys run_episode returns are a quick check of one run.
from vbar import ApproachConfig, ApproachEnv
from vbar.agents import PDAgent
from vbar.metrics import evaluate, record_episode

env = ApproachEnv(ApproachConfig(start_state=(0, -400, 0, 0, 0, 0)))
m = evaluate(record_episode(env, PDAgent()))
print(m["success"], m["composite_score"], m["failure_label"])  # True 1.0 None
Definitions, tests and one card per metric are in docs/metrics.md.
A whole suite is run and reported with vbar.eval: every (scenario, seed) of the suite in
parallel, one JSON-lines result per run with a provenance hash, and a report that refuses a
partial suite and gives success rates with exact intervals, interquartile means with stratified
bootstrap intervals and safety metrics by their unsafe tails. The core suite core-v1 holds the
headline benchmark: the V-bar and R-bar approaches, the on-axis docking, the run time assurance
docking and the inspection, each with and without navigation noise.
python -m vbar.eval run --suite core-v1 --agent vbar.agents:DriftAgent --workers 8 --out drift.jsonl
python -m vbar.eval report drift.jsonl --markdown drift.md
See docs/evaluation.md.
Any object with a name, a reset(view, rng) method and an act(obs, info) method that returns
three numbers in [-1, 1] is an agent:
import numpy as np

from vbar import ApproachConfig, ApproachEnv, run_episode
from vbar.agents.sign_check import sign_check


class SpringAgent:
    name = "spring"

    def reset(self, view, rng=None):
        self.max_accel = view.max_accel
        self.hold_point = np.array(view.goal["hold_point"])

    def act(self, obs, info):
        # Critically damped at 0.01 rad/s, nine times the orbital rate, so the CW terms are small.
        a = 1e-4 * (self.hold_point - obs[:3]) - 0.02 * obs[3:6]
        return np.clip(a / self.max_accel, -1.0, 1.0)


print(sign_check(SpringAgent()).passed)  # True
env = ApproachEnv(ApproachConfig(start_state=(0, -400, 0, 0, 0, 0)))
print(run_episode(env, SpringAgent())["captured"])  # True
reset receives a read-only AgentView with the scenario's public description (time step, mean
motion, actuator limits, goal and constraints) and a random stream for the agent's own use. obs
comes from the navigation sensor and info holds only the time, so a controller never sees the
true state. The agent's stream is seeded by run_episode(env, agent, seed, agent_seed)
independently of the episode seed. Seeds not given are drawn (128 bits) and returned in the
result, so the run can be repeated; scored comparisons keep them drawn, since an agent can find a
small seed by matching its first observation against the public scenario
(docs/environment.md).
vbar.agents includes classical controllers to compare against. Each page gives the method, its
limits and how it is tested.
| Agents | Method | Page |
|---|---|---|
PDAgent |
CW-cancelling proportional-derivative law to the hold point | environment.md |
LQRAgent, LQGAgent |
discrete LQR to the hold point, and the same law on a Kalman filter estimate | lqr.md, lqg.md |
CWTrackingAgent, LyapunovAgent |
Lyapunov tracking on the CW model and on a declared two-body model | lyapunov.md |
TwoImpulseAgent |
two-impulse CW targeting | two-impulse.md |
GlideslopeAgent |
pulsed glideslope approach | glideslope.md |
ElementAgent, TorvaAgent, FehseSequenceAgent, NominalTrackingAgent |
transfers, fly-arounds, forced motion and nominal tracking | trajectory-elements.md |
ElevationTimedAgent, PilotAgent |
Space Shuttle elevation-timed burns and manual pulses | shuttle-baselines.md |
LambertAgent |
two-impulse targeting by Lambert's problem (vbar.dynamics.lambert.lambert) |
lambert.md |
MissionManagerAgent |
a timeline of modes with gates, contingencies and an abort | mission-manager.md |
MPCAgent (vbar.agents.mpc) |
hold-point MPC with keep-out rows sampled within each step and an optional certified terminal set | mpc.md |
NMPCAgent (vbar.agents.nmpc) |
nonlinear MPC by multiple shooting on a declared dynamics model | nonlinear-mpc.md |
PiecewiseAffineMPCAgent (vbar.agents.mpc_pwa) |
box-constrained regulator solved once as a multiparametric QP, then a table lookup | piecewise-affine-mpc.md |
FuelMPCAgent (vbar.agents.mpc_fuel) |
least 1-norm delta-v plan to rest at the hold point, planned again at every decision | mpc-fuel.md |
ClfCbfAgent (vbar.agents.clf_cbf) |
one QP per decision with a Lyapunov decrease row and a keep-out barrier row | clf-cbf.md |
Mutant(agent, kind, severity) wraps any of them with one deliberate defect, to check that the
metrics catch it (mutants.md).
vbar.oracles gives what the baselines are scored against: certified fuel bounds from the primer
vector and a finite-thrust dual bound (FuelOracle, bounds_for), primer-vector certificates, the
minimum-time and passing-side oracles, and OracleAgent with expert_dataset for expert
trajectories (oracles.md,
oracle-certificates.md,
minimum-time-oracle.md,
passing-side-oracle.md,
expert-datasets.md).
ApproachEnv follows the Gymnasium API (reset(seed=...), step(action)), by default with a
Box(-1, 1, (3,)) action space and a 6-element observation, and passes Gymnasium's environment
checker, so it works with standard RL libraries. Importing vbar registers it:
import gymnasium as gym

import vbar  # noqa: F401

env = gym.make("vbar/Approach-v0")
obs, info = env.reset(seed=0)
obs, reward, terminated, truncated, info = env.step(env.action_space.sample())
Train with a library reward, whose terms follow the benchmark metrics and whose discount is declared per second, so the task does not change with the step length (docs/rewards.md):
from vbar import ApproachConfig, ApproachEnv
from vbar.rewards import Reward

reward = Reward(tau=3600.0, success_bonus=10.0, fuel_weight=1.0, entry_weights={"keep_out": 5.0})
env = ApproachEnv(ApproachConfig(reward=reward, training=True))
obs, info = env.reset(seed=0)
obs, r, terminated, truncated, info = env.step([0.0, -0.1, 0.0])
print(round(info["discount"], 6))  # discount this transition by exp(-dt / tau)
Without reward the scenario returns its legacy shaped reward (progress toward the hold point,
minus delta-v, minus a penalty for each step in the keep-out zone, plus a bonus on capture), which
is not aligned with the metrics and is not the benchmark score; score agents with vbar.metrics.
ApproachVectorEnv steps many copies as one batch (docs/vector-env.md);
the discrete bang-off-bang and burn-and-coast action modes, training-only starts and a safety
filter in the training loop are on docs/training.md, and trained networks
export to ONNX with their normalization built in (docs/policy-export.md).
Rewards and info come from the true state, so fly trained policies for scoring through
run_episode or vbar.metrics.record_episode, which pass them only the observation and the time
and refuse environments built for training.
LLMAgent wraps any model through a function you fill in, complete(messages, tools). It sends
the decision's conversation to your model client and returns a Reply (the text and the token
counts the provider reports) or just the text. text_model adapts a client that takes a prompt
string and returns text. LLMAgent has no model client of its own:
from vbar import ApproachConfig, ApproachEnv, run_episode
from vbar.agents import LLMAgent, Price, Reply, text_model


def complete(messages, tools):
    """Stand-in: replace the body with a call to your model client."""
    return Reply('{"ax": 0.0, "ay": 0.0, "az": 0.0}', input_tokens=900, output_tokens=20)


env = ApproachEnv(ApproachConfig(start_state=(0, -400, 0, 0, 0, 0)))
agent = LLMAgent(complete, name="my-model", price=Price(3.0, 15.0))
result = run_episode(env, agent)
print(agent.usage())  # decisions, model calls, tokens, cost and parse failures

plain = LLMAgent(text_model(lambda prompt: '{"ax": 0.0, "ay": 0.0, "az": 0.0}'))
To fly an episode with your own model, fill in complete() in examples/llm_controller.py, copy
.env.example to .env, set VBAR_LLM_API_KEY and VBAR_LLM_MODEL there, and run
python examples/llm_controller.py from a clone of the repository. With no key it flies a scripted
stand-in offline. python-dotenv, installed by pip install "vbar[llm]" (not in the 0.7.0
release, where pip install python-dotenv does the same), reads the file; without it the example
reads the OS environment only, and a variable already set there wins over the file. .env is
git-ignored.
LLMAgent reads no API key or model name; the function you write reads its own
(API keys). The
vbar command, from the next release, is the one part of V-BAR that reads a key: VBAR_LLM_API_KEY
when it is set, otherwise the key vbar setup stored.
Each step's prompt gives the frame, the mean motion, the task's goal and constraints in words, the
current state measured against them (offsets from a docking port's axis, coverage of an
inspection) and the thrust limit, and asks for a JSON reply such as
{"ax": 0.1, "ay": -0.5, "az": 0.0}; a reply that cannot be parsed counts as a parse failure and
the spacecraft coasts for that step. The agent flies every task kind of the catalogue. The prompt
is configurable, the agent can offer tools (coast and transfer predictions from its own
observation), every run can be recorded and replayed without the model, and an optional belief
check measures whether the model's stated reasoning matches its inputs. The simulation clock is
paused while the model answers, unless the run is in real time
(docs/llm-agents.md).
Agents can also run in another process or language through the agent server (with Python and
MATLAB clients), LLM harnesses can fly episodes through a Model Context Protocol tool server
(docs/remote-agents.md),
and planners can submit whole plans to an external verifier
(docs/agents.md). Every agent
should pass the sign-convention check, vbar.agents.sign_check.sign_check(agent), before it is
scored.
The dynamics can be used without the environment:
import numpy as np
from vbar.dynamics import make_dynamics

dyn = make_dynamics("twobody_j2", altitude=500e3, inclination=np.radians(51.6))
dyn.reset([0.0, -200.0, 0.0, 0.0, 0.0, 0.0])  # Hill-frame state, m and m/s
x, _ = dyn.advance([0.0, 0.0, 0.0], 600.0) # hold zero acceleration for 600 s| Model | What it is |
|---|---|
"cw" |
Clohessy-Wiltshire: relative motion linearized about a circular orbit, with the exact solution for an acceleration held constant over a step. Accurate while the separation is small compared with the orbit radius. |
"twobody" |
Nonlinear relative motion under point-mass gravity, integrated numerically in a form that keeps the relative state accurate far below a millimetre. |
"twobody_j2" |
The same with Earth's oblateness (J2). The target starts on a circular orbit in J2 mean elements, and the Hill frame includes the extra rotation J2 causes. |
Also included, each documented in docs/:
- differential drag and solar radiation pressure with Earth shadow for the two-body model
(
vbar.dynamics.perturbations), and elliptic or phased target orbits; - the Yamanaka-Ankersen elliptic model, curvilinear Clohessy-Wiltshire and linearized two-body
motion with J2 (
vbar.dynamics.relative); transition matrices from the variational equations; model-error measures between models (vbar.dynamics.fidelity); - Earth-Moon three-body models: the circular restricted problem, linear models about libration
points and periodic orbits, and the bicircular Sun perturbation (
vbar.dynamics.cr3bp), with halo-orbit seeds, correctors, continuation and Floquet analysis (vbar.dynamics.periodic_orbits); - Kepler propagation for any conic (
vbar.dynamics.kepler), conversion between states and classical elements for elliptic orbits, and J2 secular rates with a first-order mean-osculating element map (vbar.dynamics.mean_elements); - a replay of flown orbits through these models (
vbar.flightdata): GRACE-FO's two satellites on 3 December 2019, 182 km apart, stay inside an error bound stated before the run over ten orbits on the J2 and drag rungs, a check of the nonlinear models, not of Clohessy-Wiltshire. - published results rebuilt from their papers (
vbar.reproductions): Ariba et al.'s minimum-fuel V-bar glideslope by linear programming (vbar.agents.glideslope_lp) on Hablani's case, compared number by number withpython -m vbar.reproductions.
Earth uses the WGS 84 constants; a Kerbin body with KSP's values is available for comparison with KSPDG.
vbar.games rebuilds KSPDG's pe1 pursuit-evasion problem on two-body dynamics, with KSPDG's
observation list, action dictionary and agent interface, so an agent written for KSPDG runs
unchanged, headless, faster than real time and in parallel. The four starts are KSPDG's mission
saves; the evaders are V-BAR's versions of KSPDG's public evaders.
from vbar.games import PE1_E3_I3_Env, AgentEnvRunner
from vbar.games.pursuers import VelocityMatchingPursuer

results = AgentEnvRunner(VelocityMatchingPursuer(), PE1_E3_I3_Env, {"episode_timeout": 30.0}).run()
print(results["agent_env_results"]["weighted_score"])
A KSPDG agent file runs with no change at all through python -m vbar.games.compat my_agent.py,
which gives KSPDG's import names to V-BAR's classes in that process. The scenarios are also Gymnasium
environments (vbar/PursuitEvasionE3I3-v1 and the others); see
docs/pursuit-evasion.md.
Beyond the approach above, vbar.scenarios holds twenty-three scenarios built from specs: the
V-bar, R-bar and orbit-normal approaches with a dwell at the hold point, docking as a contact
event with mechanism windows and corridors (with on-axis, Shuttle-corridor and Sun-window
variants), an offset port, an inertially pointing target, the run time assurance docking task,
inspection under lighting and shadow, the ISS-class closing and R-bar acquisition, a berthing
box, and the Shuttle's flown profiles (ORBT, the pitch-manoeuvre hold, the twice-orbital-rate
transition, the V-bar final approach, the HST grapple approach and the separation fly-around),
four comparison tasks rebuilt from their papers (the AFRL docking and illuminated inspection, the
SpaceGym docking and rendezvous), a departure from an aft port, and the capture of a tumbling
upper stage with five tumble presets (flat spin, coning, near the separatrix, next to the
intermediate axis, a dead stage librating in the gravity gradient). Each has a Gymnasium ID, and
all but the comparison tasks, the departure and the capture have :nav1 and :nav2 variants:
import gymnasium as gym

from vbar.scenarios import SCENARIOS, make, seeds

print(sorted(SCENARIOS))
env = make("docking:axis")
print(env.scenario_id)
env.reset(seed=seeds("docking:axis", "validation", 10).seed(0))
env = gym.make("vbar/ApproachRbar-v1")
Identifiers name every option that changes a result, seeds come in train, validation and hidden test splits, and suites list the runs a report must cover in full (docs/scenarios.md).
Three real rendezvous events are rebuilt from public reports with their failures as fault models:
the Progress M-34 collision with Mir, the ETS-VII thruster anomaly and the DART collision, each
with a :nominal variant without the failure
(docs/reconstructions.md).
How each part is built, with its equations, methods, assumptions and limits, is in docs/, one page per part; the index there lists the pages.
python -m pytest -q          # the default run, without the whole-episode audits
python -m pytest -q -m slow  # the whole-episode scenario audits
The models are tested against closed-form solutions, an independent integrator and published textbook examples (listed in the validation page). CI runs the tests on Linux, macOS and Windows.
See CONTRIBUTING.md.
If you use V-BAR in your work, please cite it using the metadata in CITATION.cff (GitHub's "Cite this repository" button gives BibTeX and APA). Each release is archived on Zenodo; the DOI 10.5281/zenodo.23632751 always resolves to the latest version, and each version has its own DOI on that page.